In the rush to integrate machine learning into enterprise workflows, we have collectively fallen into a trap of convenience. For years, the North Star metric for regression models has been Mean Squared Error (MSE). It is elegant, mathematically tractable, and easy to bake into automated training pipelines. However, for leaders tasked with deploying predictive intelligence into high-stakes environments—such as supply chain logistics, energy grid management, or customer churn forecasting—relying solely on MSE is a strategic liability.
The fundamental issue is that MSE treats every error as a penalty based on distance, typically squaring the difference between predicted and actual values. This creates a "blind spot" in decision-making: it tells you how far off you are on average, but it fails to communicate the probabilistic uncertainty inherent in the real world. In a business context, being "average" is rarely the objective. You need to know the risks of the tails.
The Mirage of Average Performance
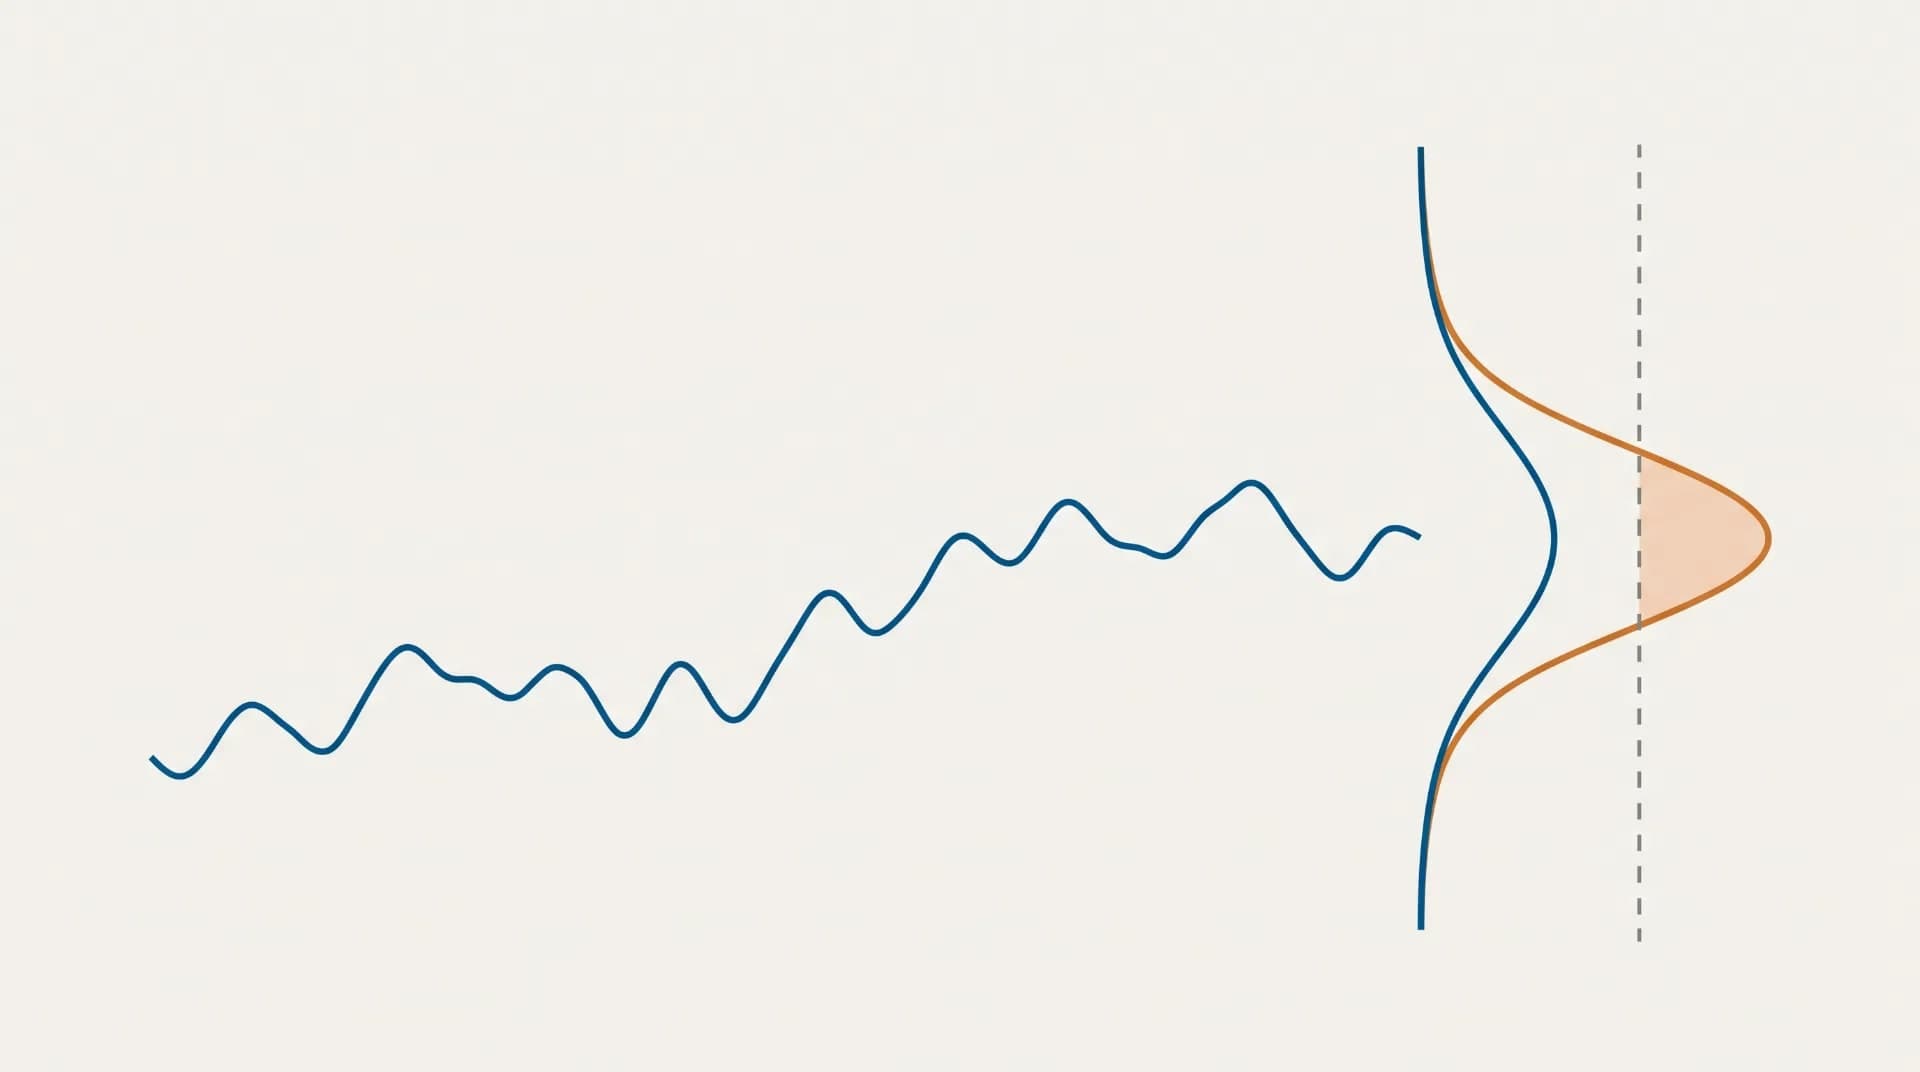
When your data science team presents a model with a "low MSE," they are essentially showing you a point estimate. They are saying, "Based on historical trends, we expect this value." But in a complex system, the most dangerous outcomes are not the average ones; they are the outliers.
If you are a logistics provider, your Digital Transformation efforts likely include automated demand forecasting. If your model averages the error, it might perform well during periods of stability but fail catastrophically during a supply chain shock or a sudden market shift. Because MSE penalizes large errors heavily by squaring them, the model becomes overly cautious, attempting to "chase" the average and effectively smoothing over the volatility that actually dictates your ROI.
When we prioritize MSE as the ultimate benchmark, we encourage a culture of "black box" optimization. This has several downstream effects on business operations:
- Risk Miscalculation: Strategic decisions are made under the assumption that the model’s point forecast is a ground truth, ignoring the volatility that could lead to inventory stockouts or resource shortages.
- False Confidence in Automation: AI Agents and automated systems rely on these forecasts to trigger downstream processes—like reordering stock or adjusting customer pricing. If the confidence interval is ignored, the automation behaves with a misplaced sense of certainty.
- Metric Displacement: Engineering teams optimize for the leaderboard (the lower the MSE, the better), inadvertently ignoring the business reality that a small error in one direction might be manageable, while a small error in the other direction could cost the company millions.
Moving Toward Probabilistic Intelligence
To move beyond the limitations of MSE, businesses must pivot toward Probabilistic Forecasting. This approach doesn't just ask, "What is the most likely number?" It asks, "What is the distribution of all possible outcomes?" By shifting the focus from point estimates to confidence intervals and probability density, you arm your leadership team with a range of scenarios rather than a single, potentially misleading number.
This is particularly critical for CRM and customer lifecycle management. Predicting whether a customer will churn shouldn’t result in a binary "yes/no" output. Instead, a probabilistic model provides a churn risk score—for example, a 70% probability of churn within the next 30 days. This allows your sales and support teams to triage their efforts, focusing on high-risk, high-value accounts where the uncertainty suggests an intervention is required.
As AI continues to transition from an experimental phase to a core operational pillar, the adoption of more nuanced metrics is essential. We are entering an era where Custom Software architectures must be designed to accommodate the reality that the future is inherently probabilistic. When your internal systems can communicate not just the "what," but the "how certain are we," your business becomes inherently more resilient.
Consider the ROI implications of this shift. While building probabilistic models requires more upfront architectural effort than simply minimizing MSE, the reduction in downside risk is substantial. A model that understands its own uncertainty is a model that can be "switched off" or flagged for human intervention before it makes a high-cost mistake. This is the difference between fragile automation and a robust, scalable digital ecosystem.
The Path to Operational Resilience
For business leaders, the takeaway is clear: do not take model performance metrics at face value. When your teams report on the accuracy of your predictive infrastructure, ask the difficult questions. Ask about the distribution of errors. Ask how the model performs during periods of low volatility versus high volatility. And critically, ask how the model handles scenarios where it hasn't seen the data before.
The goal of modern AI is not perfection; it is a calculated understanding of the terrain. By moving beyond MSE, you stop managing to a mathematical abstraction and start managing to the realities of your market. This requires a shift in how you conceptualize your data stack, ensuring that uncertainty is treated as a first-class citizen in every Automation workflow you deploy.
The landscape of decision-making is shifting from intuition-led to data-supported, but the quality of that support depends on the rigor of the underlying math. At AOODAX, we help enterprises architect robust AI solutions that prioritize long-term reliability over superficial accuracy metrics, ensuring your AI agents are built on a foundation of sound, probabilistic reasoning.